
 Multi-Vendor & Complex SaaS Marketplaces
 Modern Headless & Jamstack Web Development
 High-End Corporate & Specialized Business Websites
 Advanced API, Checkout & Database Troubleshooting
Viral Tweet Crashed Your Site? Nginx Load Balance on Vultr
One viral tweet took your single server down. Learn how horizontal scaling with an Nginx load balancer across three Vultr nodes stops the outage—and when Australian teams should book Fixwebnode for remote setup.
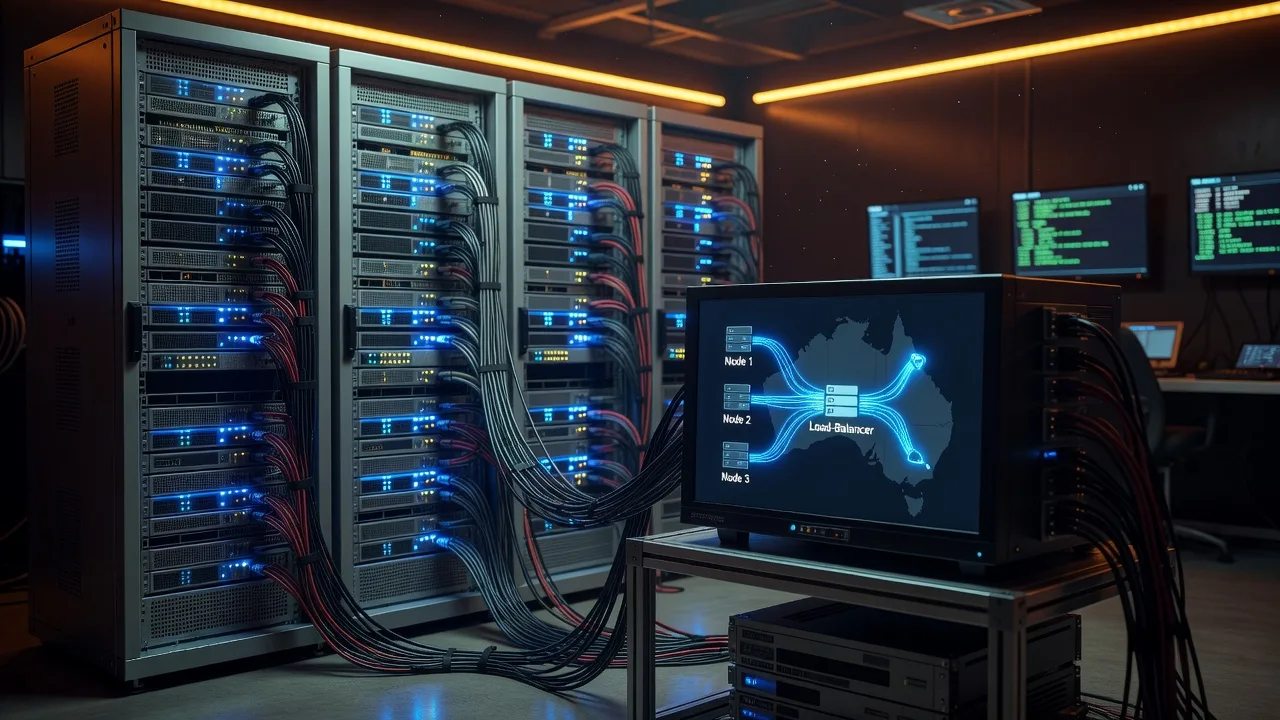
If a random tweet sent a flood of visitors and your site fell over, you do not have a “marketing problem”—you have a capacity problem. A single Vultr (or any) VPS will saturate CPU, RAM, or connection limits under sudden traffic. This guide walks Australian site owners and small businesses through diagnosing that failure mode and configuring Nginx as a load balancer across three Vultr nodes so traffic is shared instead of crushing one box. Fixwebnode provides remote Linux server support for this exact work: horizontal scaling, Nginx upstreams, health checks, and stabilising production under spike load.
We assume Ubuntu 22.04/24.04 on Vultr, root or sudo access, and three application nodes plus one balancer (or one of the three acting as balancer if you must start lean). Delivery is remote—SSH, configs, and verification—so teams anywhere in Australia can follow the same runbook.
Why a viral spike kills a single server
When one post goes viral, concurrent connections jump faster than vertical upgrades can help. PHP-FPM workers queue, MySQL connections max out, Nginx file descriptors climb, and visitors see timeouts or 502/503. Horizontal scaling—spreading identical app instances behind a load balancer—is the standard fix. Nginx is a solid, well-understood choice for Layer 7 balancing, SSL termination, and health-aware upstreams on Vultr.
How do I stop a viral-traffic crash with Nginx on three Vultr nodes in Australia?
Put Nginx in front as a reverse proxy load balancer, point DNS at the balancer, and run the same application stack on three Vultr backend nodes. Use least_conn or round-robin upstreams with active health checks so dead nodes are skipped. If configs, SSL, sessions, or database write paths are unclear, book remote help from Fixwebnode rather than experimenting on a live outage.
| Symptom | Quick fix | When to call Fixwebnode |
|---|---|---|
| Site times out only under spike | Add backends + Nginx upstream | You cannot spare downtime to re-architect |
| 502 Bad Gateway after balancing | Check upstream ports, firewall, health | Backends flap or SSL breaks mid-cutover |
| Logged-in users lose session | Sticky cookies or shared session store | Cart/auth must stay correct under load |
Common issues after a viral crash (unique failure modes)
1. Single-node saturation: CPU, workers, and file descriptors
Symptoms: load average spikes, too many open files, PHP-FPM max children reached, Nginx 503, SSH barely responds. One VPS absorbed 100% of the tweet traffic.
2. Load balancer 502/504 with healthy-looking backends
Symptoms: balancer returns 502 Bad Gateway or 504 Gateway Timeout while each app node answers curl locally. Causes include wrong upstream port, UFW blocking the balancer IP, slow PHP, or missing proxy_pass headers.
3. Session and cart loss across nodes
Symptoms: users bounce between backends and get logged out, empty carts, or CSRF failures. Local file sessions on each Vultr node are not shared.
4. Uneven traffic and “dead” node still receiving hits
Symptoms: one node at 100% CPU while others idle; or a crashed node still in the pool because passive checks never removed it.
Fix 1 — Diagnose the crash and prepare three Vultr app nodes
Confirm the outage is capacity, not only a bad deploy. On the original server:
Step 1 — Capture load and connection pressure
uptime
free -h
ss -s
sudo journalctl -u nginx -n 100 --no-pager
sudo tail -n 100 /var/log/nginx/error.log
sudo tail -n 100 /var/log/php*-fpm.log
Look for worker exhaustion, upstream timeouts, and OOM kills.
Step 2 — Provision three identical app nodes on Vultr
Create three Ubuntu instances in the same region (for lower latency within Australia-facing traffic, choose a region that matches your audience). Install the same stack (Nginx or only PHP-FPM + app, matching your architecture). Sync code and env the same way on each host.
Step 3 — Open only what the balancer needs
sudo ufw allow OpenSSH
sudo ufw allow from BALANCER_PRIVATE_IP to any port 80
sudo ufw allow from BALANCER_PRIVATE_IP to any port 443
sudo ufw enable
sudo ufw status
Prefer Vultr private networking between balancer and backends so app ports are not public.
Step 4 — Verify each backend answers locally
curl -I http://127.0.0.1/
curl -I http://127.0.0.1:8080/
Use the real listen port your app uses. Fix application errors here before balancing.
When to call Fixwebnode: if nodes diverge (different PHP versions, missing env, broken deploys) or you need a safe cutover plan during business hours in Australia, remote specialists can standardise images and roll the change with rollback points.
Fix 2 — Configure Nginx as the load balancer across three nodes
On the balancer host (fourth small Vultr instance, or a dedicated role), install Nginx and define an upstream pool.
Step 1 — Install Nginx
sudo apt update
sudo apt install -y nginx
sudo systemctl enable --now nginx
Step 2 — Define upstream with least connections
sudo nano /etc/nginx/conf.d/upstream-app.confupstream app_backends {
least_conn;
server 10.0.0.11:80 max_fails=3 fail_timeout=30s;
server 10.0.0.12:80 max_fails=3 fail_timeout=30s;
server 10.0.0.13:80 max_fails=3 fail_timeout=30s;
}Replace private IPs with your Vultr private addresses. least_conn suits uneven request cost better than plain round-robin during a viral spike.
Step 3 — Reverse proxy site config
sudo nano /etc/nginx/sites-available/lb-siteserver {
listen 80;
server_name example.com www.example.com;
location / {
proxy_pass http://app_backends;
proxy_http_version 1.1;
proxy_set_header Host $host;
proxy_set_header X-Real-IP $remote_addr;
proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
proxy_set_header X-Forwarded-Proto $scheme;
proxy_connect_timeout 5s;
proxy_send_timeout 60s;
proxy_read_timeout 60s;
}
}sudo ln -sf /etc/nginx/sites-available/lb-site /etc/nginx/sites-enabled/
sudo nginx -t && sudo systemctl reload nginxStep 4 — Point DNS at the balancer
Lower TTL ahead of time if you can. Update A/AAAA records to the balancer public IP. Keep the old server available until health checks pass.
Step 5 — Verify distribution
for i in 1 2 3 4 5 6; do curl -s -o /dev/null -w "%{http_code}\n" http://example.com/; done
sudo tail -f /var/log/nginx/access.log
On each backend, watch access logs to confirm all three receive traffic.
When to call Fixwebnode: 502/504 after reload, mixed HTTP/HTTPS redirects, or you need TLS termination with Let’s Encrypt on the balancer while backends stay HTTP on private net.
Fix 3 — Stop session loss (sticky sessions or shared store)
File-based PHP sessions on three disks will break logins under round-robin.
Step 1 — Short-term: Nginx sticky cookie (ip_hash or map)
upstream app_backends {
 ip_hash;
 server 10.0.0.11:80 max_fails=3 fail_timeout=30s;
 server 10.0.0.12:80 max_fails=3 fail_timeout=30s;
 server 10.0.0.13:80 max_fails=3 fail_timeout=30s;
}
ip_hash pins a client IP to one backend. It is a stopgap; mobile carriers and corporate NATs can still mis-pin.
Step 2 — Proper fix: shared sessions (Redis)
On a small Redis instance (or one hardened node):
sudo apt install -y redis-server
sudo systemctl enable --now redis-server
redis-cli ping
Point PHP or your app session driver at Redis so any backend can serve any user. Reload PHP-FPM after config changes:
sudo systemctl reload php8.3-fpm
# or: sudo systemctl reload php8.2-fpm php8.1-fpm
Step 3 — Verify login survives multiple requests
curl -c /tmp/cj -b /tmp/cj -s -o /dev/null -w "%{http_code}\n" https://example.com/accountRepeat and confirm session cookie remains valid while logs show different upstreams (if not using ip_hash).
When to call Fixwebnode: WooCommerce, custom auth, or multi-node cache invalidation needs a coherent design—not just a cookie flag.
Fix 4 — Health checks so dead nodes drop out
Passive max_fails helps; active checks are better when a node is up but returning 500s.
Step 1 — Simple health endpoint on each app
Expose a lightweight route (static file or app /healthz) that returns 200 only if the app can reach its DB.
Step 2 — Open-source Nginx: mark down via fail timeout and monitor
curl -s -o /dev/null -w "%{http_code}\n" http://10.0.0.11/healthz
curl -s -o /dev/null -w "%{http_code}\n" http://10.0.0.12/healthz
curl -s -o /dev/null -w "%{http_code}\n" http://10.0.0.13/healthz
Automate with a cron or monitoring agent; remove a bad server from the upstream block and reload:
sudo nginx -t && sudo systemctl reload nginxStep 3 — Watch error log during a controlled load test
sudo tail -f /var/log/nginx/error.log
# from a workstation with hey or ab, generate modest load—not a second denial-of-service
Confirm failed peers are skipped and recover after fail_timeout.
When to call Fixwebnode: flapping health, false positives taking capacity offline during peak Australian evening traffic, or you want managed monitoring wired to the balancer.
Extra hardening while you scale
Raise file descriptors on busy nodes
sudo mkdir -p /etc/systemd/system/nginx.service.d
printf '[Service]\nLimitNOFILE=65535\n' | sudo tee /etc/systemd/system/nginx.service.d/limits.conf
sudo systemctl daemon-reload
sudo systemctl restart nginx
Confirm PHP-FPM pool sizing on each backend so three nodes together cover peak workers without thrashing RAM.
ps aux | grep php-fpm
sudo grep -E 'pm\.|max_children' /etc/php/*/fpm/pool.d/www.conf
Database reality check: three web nodes can overwhelm one small MySQL/MariaDB. Add connection limits, a primary with read replicas if needed, or move DB to a sized managed instance before the next viral hit.
When DIY is enough vs when to book Fixwebnode
DIY is enough if you already run Ubuntu on Vultr, can SSH confidently, your app is stateless or you can enable Redis sessions, and you can schedule a short maintenance window. Follow the numbered steps above, keep a rollback DNS TTL, and document private IPs and upstream blocks.
Book Fixwebnode when the site is still down, you lack a second pair of eyes for cutover, SSL or admin cookies break after proxy headers, the database is the real bottleneck, or you need a repeatable three-node pattern (images, deploys, health checks) rather than a one-off edit. Fixwebnode is a direct specialist provider for remote Linux and server support across Australia—not a freelance marketplace. See where support is offered on the service areas page, then talk through your Vultr layout and traffic pattern.
Stabilise before the next viral post
A random tweet should not equal an outage. Horizontal scaling with Nginx in front of three Vultr nodes spreads load, health-aware upstreams remove sick backends, and shared sessions keep logins intact. Work through diagnostics, upstream config, session strategy, and verification commands above; if you need the change done safely under pressure, start a conversation with Fixwebnode via Ubuntu Linux server support and map the balancer design to your stack before the next spike.