







 Multi-Vendor & Complex SaaS Marketplaces
 Modern Headless & Jamstack Web Development
 High-End Corporate & Specialized Business Websites
 Advanced API, Checkout & Database Troubleshooting
Terraform IaC Multi-Server Linux Deployment — Remote Worldwide
Automate multi-server Linux fleets with production-grade Terraform scripts — delivered remotely worldwide.
We write, harden, and hand over reusable Terraform modules so your VMs, networks, and baseline configs deploy the same way every time—cutting manual rebuild risk for SaaS, clinics, and multi-region ops teams. Prefer a fixed-scope quote from a direct provider, not marketplace noise.
Power up your support path anytime: fixwebnode.com.au/contact-support or chat with us for a scoped plan.
- Idempotent multi-server Linux stacks
- State, secrets, and apply safety built in
- Remote delivery with plain-English handoff
About this service
Ship repeatable multi-server Linux infrastructure with Terraform Infrastructure as Code—scoped, tested, and delivered remotely worldwide by Fixwebnode. We replace one-off SSH click-ops with versioned modules so new environments, DR rebuilds, and capacity bumps land in minutes instead of nights of drift.
What You'll Get
- Production Terraform root + modules - Clean HCL for compute, networking, security groups/firewall rules, and Linux bootstrap for multi-node layouts.
- Remote state & locking design - Backend layout (e.g. S3/GCS/Azure + DynamoDB/locks or equivalent) so two engineers never corrupt the same state.
- Idempotent Linux provisioning path - cloud-init/user-data or provisioner-safe bootstrap for packages, users, SSH hardening, and baseline agents.
- Plan-first delivery artefacts - Documented terraform plan samples, variable maps, and environment separation (dev/stage/prod).
- Destroy-safety & import notes - Lifecycle guards, import recipes for brownfield hosts, and runbooks for partial apply recovery.
- Handoff package - README, make/task targets or CI skeleton, and a short walkthrough so your team owns the next apply.
Serving Remote & surrounds
This offer exists for distributed technical teams who run Linux estates across cloud regions and need one source of truth—not a local storefront clone. Demand spikes when product launches, audit windows, or end-of-quarter capacity freezes collide with manual server builds. We work fully remote worldwide; on-site only where practical for rack or hybrid edge gear.
- SaaS and product engineering squads standardising app, worker, and bastion tiers before a release freeze
- Healthcare, telehealth, and clinic IT groups needing reproducible non-prod mirrors of production Linux stacks for change control
- Remote-first MSPs and internal platform teams absorbing brownfield VMs into Terraform without a weekend outage
How We Work
- Step 1: Reach Out - You describe target providers (AWS/GCP/Azure/on-prem API), node roles, OS images, and pain (drift, slow rebuilds, failed DR drills). We listen first.
- Step 2: Tailored Plan - Fixed-scope quote: module boundaries, state backend, secrets approach, and acceptance checks—no open-ended bidding.
- Step 3: We Deliver - We author HCL, validate with plan/apply in a safe workspace, wire Linux baseline, and capture metrics (apply duration, node count, failed resource rate).
- Step 4: Confirm & Follow-up - Plain-English handoff, optional maintenance window support, and next-environment clone guidance.
Common Issues & How to Fix Them
These are failure patterns we see constantly on multi-server Linux Terraform estates—symptoms first, then safe DIY, then when to stop.
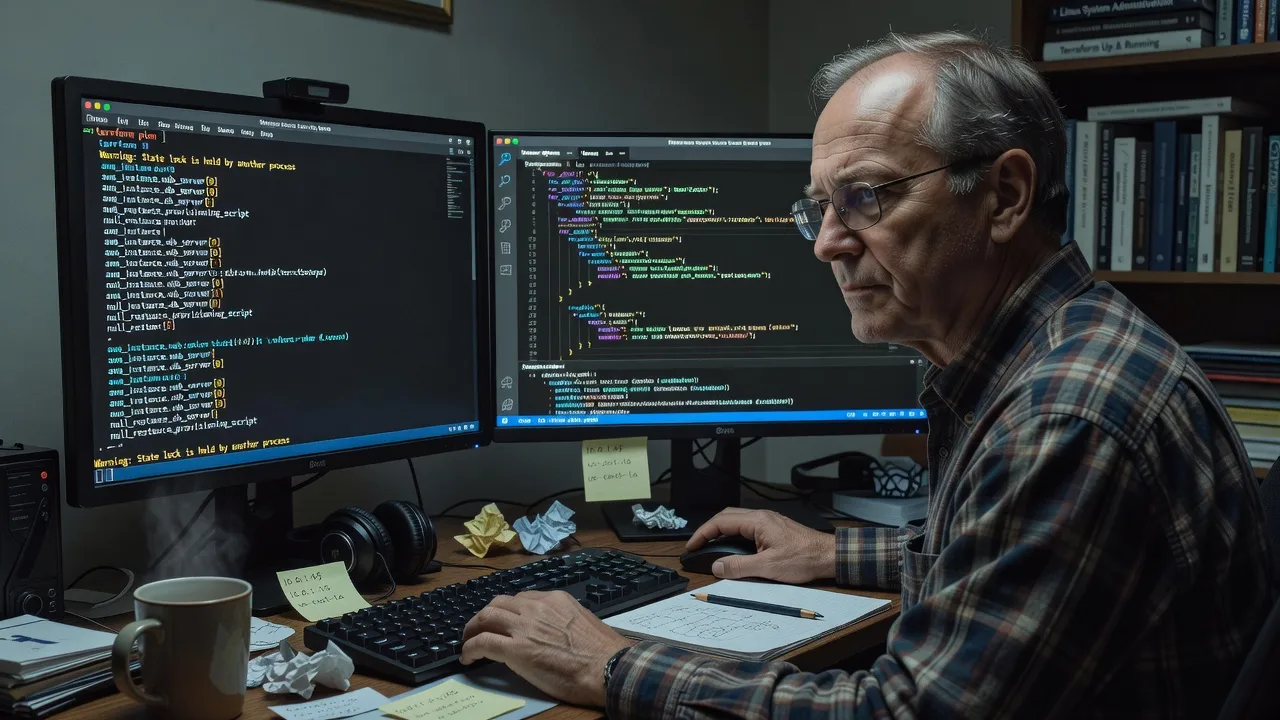
Issue 1: Stale remote state lock blocks every apply (Error acquiring the state lock)
Usually a crashed CI job or laptop sleep left a lock ID in the backend while no real apply is running—teams burn hours guessing which process owns it.
- Step 1: Run terraform plan once and copy the lock ID / Who / Operation fields from the error. Confirm no human or pipeline PID is still applying (check CI runs and ps on bastions).
- Step 2: Only if you are certain nothing is writing state, run terraform force-unlock <LOCK_ID> against the same backend config. Never unlock during an active apply.
- Step 3: Re-run terraform plan; a clean plan with no lock error and unchanged resource counts means you are clear. If the lock returns immediately, inspect backend IAM and clock skew next.
Issue 2: Provider auth works interactively but CI applies die with 401/403 on instance or network create
Local shells often inherit long-lived keys or SSO sessions; pipelines use short-lived roles missing ec2:RunInstances, custom IAM paths, or external-id conditions—symptoms show mid-apply after state already partially wrote.
- Step 1: From the same identity the pipeline uses, run a minimal read (aws sts get-caller-identity / gcloud auth list / az account show) and compare account/project/subscription to the Terraform provider block.
- Step 2: Enable TF_LOG=INFO for one failed job, locate the first AccessDenied on Create*, then tighten role policy for that action only—avoid attaching AdministratorAccess as a permanent fix.
- Step 3: Re-run terraform plan then a targeted terraform apply -target=... on a non-prod sandbox resource; success plus matching state address means auth path is fixed.
Issue 3: Count/for_each index shift recreates the wrong Linux nodes after a list edit
Teams store server names in ordered lists; inserting a host at index 0 forces Terraform to destroy/recreate later indexes—SSH host keys flip and app traffic hits half-built boxes.
- Step 1: Run terraform state list and terraform plan; if you see destroy+create on stable hostnames you did not intend to touch, stop before apply.
- Step 2: Convert list-based count to map-based for_each keyed by stable server id/name; use terraform state mv to map old addresses to new ones before any apply.
- Step 3: Confirm terraform plan shows in-place updates or zero destroys for production nodes; only then apply. Spot-check SSH fingerprints and uptime on each host.
When DIY is not enough (urgent, unsafe, recurring, or burning time), book Fixwebnode for direct professional support—no freelancers, bidding, or marketplace noise.
Expert Insights
After years of multi-node Linux Terraform on live estates, these are the non-Googleable habits that keep apply windows under control:
- Separate “identity” from “shape.” Put AMI/image id and instance type in a thin launch module; put hostname, disks, and firewall intent in a role module. When a CVE forces a fleet image bump, you change one variable and avoid rewriting networking HCL under pressure.
- Treat partial apply as a first-class incident. If apply dies after 6 of 12 instances, do not blindly re-apply. Snapshot state, run terraform state list, compare provider console inventory, and use targeted apply or import—re-running full apply mid-failure is how duplicate EIPs and orphan disks appear.
- Pin provider and module versions in the root, not only in CI cache. Floating ~> ranges that “worked last month” suddenly rewrite security-group defaults after a provider minor; we lock versions and run plan diffs in a PR before any prod apply.
- Measure what matters: track median terraform plan time, apply duration per N nodes, and count of resources with lifecycle { prevent_destroy = true } on stateful disks. When plan time doubles without resource growth, state bloat or remote backend latency is usually the culprit—not “Terraform being slow.”
- Brownfield import order: import network and IAM before compute; import compute before attached volumes with device names; never import a running node then immediately change user-data that forces replace. We document the exact address map so the first clean plan is empty.
Why Choose Fixwebnode
We are a direct technical provider for infrastructure automation—not a bid board. You get senior Linux and Terraform judgement, fixed scopes, and handoffs your on-call can run at 2 a.m. without decoding freelancers’ half-finished modules.
- ✓ Multi-server Linux IaC written for real failure modes (locks, partial apply, index shift)
- ✓ Remote worldwide delivery with optional on-site where hybrid gear demands it
- ✓ Clear packages, plan-first safety, and support via contact form or chat—no marketplace escrow theatre
Tools & Technologies
Terraform / OpenTofu; HCL modules & for_each patterns; AWS, GCP, Azure, and generic cloud-init; remote state backends with locking; Git-based review flows; Linux (Ubuntu/Debian/RHEL-family) baseline hardening; SSH CA or key rollout patterns; make/taskfile or lightweight CI plan gates; secrets via provider-native stores or external secret managers—never plaintext in state when avoidable.
Perfect For
Engineering leads, platform teams, and IT managers who need multi-server Linux environments reproducible across regions—SaaS release trains, clinic non-prod mirrors, or DR rebuilds that must finish inside a maintenance window. If manual Ansible-over-SSH drift or console click-ops is costing you nights, this remote Terraform service is built for you.
Ready to automate the next environment the same way as the last? Start at fixwebnode.com.au/contact-support or chat with us for a fixed quote.
Choose a package
Single-environment Terraform root for up to 3 Linux server roles with remote state outline and plan walkthrough.
Multi-module multi-server stack with env separation, locking backend, Linux bootstrap, and import notes for brownfield hosts.
Full multi-region or multi-tier Linux estate automation with CI plan gates, destroy-safety, DR rebuild drill support, and extended revisions.
FAQ
Yes. This service is designed for remote delivery worldwide. We work over secure screen-share and Git, with on-site attendance only where practical for hybrid or datacentre edge gear. You get a fixed-scope quote and we perform the engineering ourselves as Fixwebnode.
In most cases yes. We inventory live hosts, import into state in a safe order (network and identity before compute, volumes carefully mapped), then drive terraform plan to empty or near-empty before any change. High-risk replaces are gated behind maintenance windows and prevent_destroy on disks.
We commonly automate Ubuntu, Debian, and RHEL-family images on AWS, GCP, and Azure, plus API-driven private clouds where Terraform providers exist. Tell us your provider versions and golden image process during intake so modules match your baseline.
Treat it as an incident: we freeze further applies, reconcile console inventory against terraform state list, repair or import missing addresses, then complete with targeted applies. Blind full re-apply is avoided because it often duplicates IPs, disks, and DNS records.



